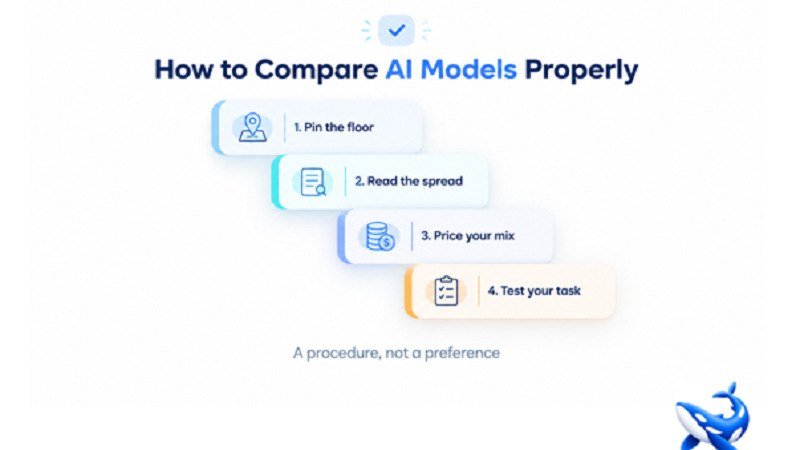
“Compare the models” is usually a Friday afternoon activity, and it shows: one ranking tab open, one favorite, one confident conclusion. On OrcaRouter‘s compare llm models page, read 2026-10-12, the twelve rows make the Friday approach fail on purpose. Eleven of the twelve models sit between an 8.0 and a 10.0 on our composite quality score, while their input prices span fifty times, from $0.60 to $30.00, and their output prices span more than ninety. A proper comparison has to be a procedure, not a preference, and it has to be run in the order that the data demands: floor first, then spread, then price, then your own test.
Here is the method, assembled from the columns the page actually gives you.
Step one — pin the floor
The first step is to set the quality floor, and it is the only step where the composite score acts as a decision. Our 0–10 composite quality score is our own judgment — we rate each model ourselves across quality dimensions such as instruction adherence, reasoning quality, output coherence, and consistency — so it is a defensible threshold, not a third-party benchmark. Anything below your floor is out; anything above it is in. On this table, the floor does less work than you might expect, because eleven of twelve rows sit inside a two-point band, so most candidates clear almost any reasonable floor.
That compression is the first finding a proper comparison has to absorb. The page is telling you that these models are close in general quality, which means the score should not be doing the final sorting. Set the floor, confirm every survivor clears it, and then stop arguing about the tenths of a point — the measurement was never that precise, and the page never claimed it was. From here on, the decision has to come from columns that still vary.
Step two — read the spread, not the headline
The second step is to read the shape of the table rather than its winners. The price spread is the loudest shape: input prices from $0.60 to $30.00, output prices from $1.98 to $180.00, and output-to-input multipliers in four bands — 3.0x for DeepSeek V4 Pro and Grok 4.7, 4.0x and 4.2x for MiniMax M2.7 highspeed and kimi-k2.6, 5.0x for the three Claude rows, Gemini 3.8 Flash and GPT-6 Sol, and 6.0x for Gemini 3.1 Pro Preview, GPT-5.4 and GPT-5.5 Pro. The multiplier matters because it determines who wins on a read-heavy mix versus a write-heavy one; a 3.0x row flatters writers, a 6.0x row flatters readers.
Two more spreads belong in the same reading. Context windows run from 205K to 1M — MiniMax M2.7 highspeed at 205K, kimi-k2.6 at 262K, Grok 4.7 at 500K, eight rows at 1M, and GPT-5.5 Pro’s window unpublished, which is a fact you should treat as a constraint, not a footnote. And the latency column has its own honesty built in: several rows sit exactly at the 10.00 s ceiling for time to first token — the measurement ceiling, not a measured coincidence — while MiniMax M2.7 highspeed measures a p50 of 3.29 s and DeepSeek V4 Pro a p50 of 1.76 s. Read the spreads, and the field sorts itself before you have chosen anything.
Three pairings in the table reward this kind of reading. Two rows share our top composite score of 10.0 yet sit five times apart on input price — Claude Fable 5.1 against Gemini 3.1 Pro Preview — which is the same-score-different-price trap the earlier articles in this series kept returning to. The two firsts belong to different models: the coding rank is led by Claude Fable 5.1 at 81.6 out of 138, while the intelligence leaderboard is topped elsewhere, so “which model is best” depends on which column you ask. And the preview-versus-stable pair, Gemini 3.1 Pro Preview against Gemini 3.8 Flash, flips the expected order, with the stable sibling ranking higher on coding. The spreads are where the table’s real stories live.
Step three — price your mix, not a token
The third step is the one most teams skip, because it is arithmetic rather than reading. The table prints four numbers per row — input price, output price, and the multiplier between them — but your decision needs a fifth number that only you can compute: your own read-to-write ratio. DeepSeek V4 Pro, priced at $0.66 for input and $1.98 for output, seems like the clear winner until you handle output-heavy workloads. Gemini 3.1 Pro Preview, at $2.00 for input and $12.00 for output, appears expensive until your workload focuses mainly on reading rather than generating. The same two rows can win and lose against each other depending on the mix.
So build the monthly spreadsheet. Estimate your input tokens and your output tokens, apply each surviving row’s rates, and rank by the resulting bill. This step also folds in the traffic column as a sanity check: seven-day volume tells you where the crowd has already landed — 512.0M tokens for DeepSeek V4 Pro, 335.5M for Gemini 3.8 Flash, 123.5M for Claude Opus 5.5 — and while popularity is not proof, a workload row with zero production history is a row with undiscovered failure modes. The bill ranks your candidates; the volume tells you which candidates have been battle-tested.
Step four — test your task, read the date
The fourth step is where the procedure leaves the page entirely. Choose the two or three options that pass the first three stages, test them using real prompts, and assess how well they handle challenging real-world scenarios, such as lengthy documents, malformed inputs, multi-step tool calls, and edge cases that caused problems with your previous model. The page can rank the field; only your traces can rank the field for your workload. This is not a formality; it is the only step that produces evidence specific to you.
And one discipline wraps around all four steps: read the date. Every latency and volume figure on the page is a rolling window — read on 2026-10-12 today, different next week — and prices change when vendors change them. A comparison that records its read date is a document you can trust later; a comparison without one is a rumor with formatting. Re-run the procedure when the numbers move, because the method is durable and the snapshot isn’t.
Why the order matters
The four steps are in this order for a reason, and swapping them produces the two classic comparison mistakes. Teams that start with price pick the cheapest plausible row and never check the floor; teams that start with rank pick the winner and never check the bill. Running the procedure as written — floor, then spread, then mix-priced bill, then your task test — makes every earlier step cheaper than the one after it, so you spend your expensive testing effort only on candidates that have already survived the cheap filters.
The order also protects you from the table’s own temptations. The composite column is a floor, not a rank, and the method treats it that way. The latency column is a snapshot with a ceiling built in, and the method treats it that way. The independent coding and intelligence ranks from an external aggregator are context for the final evaluation, and the method treats them that way. The same-score pair, the two different firsts, and the preview that lost to its own stable sibling are findings you should notice early — and then test, like everything else, on your own workload. Every column on the page earns its place, and none of them earns the last word.
The takeaway
Comparing AI models properly is a four-step procedure: pin a quality floor and let every candidate above it survive; read the price, context and latency spreads rather than a headline; price your own monthly mix across the surviving rows; and test the final two or three on your real workload. Run in that order, the procedure turns a twelve-row comparison table into a two-row decision that you can defend to a budget holder — and the date stamps everything, because read 2026-10-12 today means something different next month.
The method outlives any single snapshot. Prices fluctuate, rankings shift, and the data changes, but the evaluation process remains reliable because it never relies on a single factor to make the final decision. That is the difference between comparing models and picking favorites. See more